 Humanswith.AI · since 2019



In this article
Section 01
The Shift from SEO to AEO and GEO in 2026
AEO and GEO are overlapping industry labels for improving visibility in AI-generated answers. This guide uses an AEO benchmark to measure mentions, recommendations, and citations separately. Those outcomes can overlap with SEO work, but a search position alone does not show what an answer engine actually said.
Start with the same foundations that make a page usable in search: crawlable links, accessible text, relevant content, and consistent markup. Keep the outcome labels operational. A mention names the brand; a recommendation proposes it for a task; an owned citation links to its domain.
An answer can present a shortlist without reproducing the search-results page. Check both surfaces directly instead of assuming that a search position guarantees inclusion in the answer.
What each measurement records:
| Measurement | Unit | Success observation | Supporting work |
|---|---|---|---|
| Search performance | Query and page | Impression, click, position | Crawlability, relevance, page experience |
| Brand presence | Observed AI answer | Brand mentioned or recommended | Clear offering and supported claims |
| Source citation | Observed AI answer and URL | Supporting owned page linked | Relevant evidence and readable content |
Give the reader a reason to use the page
A general definition may be useful, but it is not enough to answer every buying question. Decide which comparison, limitation, or implementation question the target reader needs resolved.
Original evidence and first-hand experience can distinguish an answer from a generic overview. Include them when they directly support the question, and label their limits. Do not infer that every narrow query forces an engine to retrieve a page.
A page titled “What is workflow automation?” gives an answer engine little reason to cite you. A page that explains where workflow rollouts overrun budget, with real project evidence, gives the model something distinct. Original evidence becomes the asset.
Check the shortlist each engine actually returns
AI assistants can participate in vendor research, but the extent varies by buyer and product. Measure the engines your audience uses. Gemini, Google AI Overviews, and Google AI Mode are separate products and should not be treated as one result series.
Observed sources and answers can differ across engines and collection conditions. Use those observations to form hypotheses about missing evidence or unclear positioning; they do not reveal the engine's internal ranking weights.
Google's published guidance for AI search features emphasises crawlable pages, internal links, textual content, useful page experience, and structured data consistent with the visible text. Meeting the requirements does not guarantee that a page will be selected. [1]
OpenAI documents OAI-SearchBot for search and GPTBot for potential model training. Their controls are independent. Audit the relevant crawler and infrastructure permissions before interpreting a page's absence from ChatGPT search. [2]
Make approved service details and case studies accessible where they help the reader evaluate the offering. An accessible page gives a search system material it can consider; it does not guarantee a particular positioning statement or recommendation.
Inconsistent pricing, category descriptions, or product facts can make an answer harder to verify. Compare the saved response with current primary records before deciding which public page needs correction.
What this changes for the measurement stack
Rank tracking no longer answers the executive question. “Are we in the answer?” needs a different instrument.
A tracking tool can collect mentions, citations, and source URLs across a defined prompt set. Select it by its measurement coverage, exportability, and failure reporting. Review the underlying answers before interpreting a score.
Use clear headings, definitions, tables where appropriate, and applicable structured data. These help readers and software interpret the page. They do not establish why a particular model selected or omitted it.
Keep dated baseline captures and a separate change log. A person reviewing the result should be able to tell what was observed, what changed, and which collection conditions stayed constant.
Keep these checks alongside the benchmark:
- Whether the target page is publicly accessible and eligible for the relevant search surface.
- Whether a quoted claim is supported by a dated source or a documented internal record.
- Whether a referral or CRM outcome is actually linked to an observed visit or declared discovery source.
Use the following process to build a baseline your team can repeat and review.
Section 02
What is an AEO benchmark?
An AEO benchmark measures whether AI answers mention your brand, recommend it, and cite your pages across a fixed set of buyer questions. Start with a versioned prompt list, collect answers separately for each engine and market, preserve the cited URLs, and repeat the same test after a documented change. Report the number of successfully observed answers alongside every rate.
A useful benchmark freezes the prompts, separates engines, saves the full answers, and tracks competitors in the same responses. Record the collection date, language, actual location, product or model, search mode, and session conditions. Keep Gemini, Google AI Overviews, and Google AI Mode in separate series. A prompt that mentions ChatGPT but was answered by another engine belongs to the engine that actually produced the answer.
The benchmark should not chase every possible query. It should focus on questions a real buyer asks before contacting sales. Discovery prompts matter, but evaluation prompts matter more. A buyer asking “best vendor for this use case” is closer to revenue than a buyer asking for a broad definition.
Preserve the pre-change observations before editing content. Measurement and execution may share tools, but the evidence must remain attributable to the correct version and time window.
Section 03
Key Metrics for Benchmarking AI Visibility
AI visibility becomes measurable when you count recommendations, citations, and accuracy. A ranked URL shows classic search performance. It does not prove that an AI system names your brand when a buyer asks for vendors.
Brand mention rate
For this benchmark, brand mention rate is the number of successfully observed answers that name the brand divided by all successfully observed answers in the same engine, market, prompt set, and time window, multiplied by 100. Count each answer once, even if it names the brand repeatedly. Record failed requests and missing captures as not measured, and report measurement coverage separately. This rate is different from the brand's share of all competitor mentions.
Three rules keep the number honest.
- Freeze the prompt set. Changing wording between cycles breaks comparability.
- Log every run. Model outputs drift, so a single answer proves little.
- Separate the engines. A strong result in Perplexity and a weak result in ChatGPT require different fixes.
Segment the metric by intent stage. Discovery prompts behave differently from evaluation prompts. Evaluation prompts deserve heavier attention because they influence the shortlist.
If you measure a company site and a founder site, declare which domains belong to each subject. Report separate outcomes before aggregating anything; a citation of one property is not automatically a citation of the other.
Citation frequency and source attribution
Owned-domain citation rate is the percentage of successfully observed answers that contain at least one citation linking to a domain you own. Count an answer once for this rate and preserve every cited URL for page-level analysis. A brand mention, an explicit recommendation, an owned-domain citation, and a third-party citation supporting the brand are separate observations. A completed answer with no owned citation counts as zero; a failed capture is not measured. For Google AI Overviews, also record whether an Overview appeared and report that appearance rate separately.
Use the following fields to make each observation auditable:
| Field | What to record | Why it matters |
|---|---|---|
| Test identity | Prompt ID, exact wording, prompt-set version, intent | Keeps repeated tests comparable |
| Collection conditions | Engine, product or model, search mode, date, language, actual location | Separates market and engine effects |
| Observation status | Answered, no Overview observed, or not measured with a reason | Prevents failed captures becoming false negatives |
| Brand mention | Brand named in the answer, yes/no | Measures presence without requiring a link |
| Recommendation | Explicitly recommended, yes/no; shortlist position where meaningful | Separates selection from a passing mention |
| Owned citation | Owned domain cited, yes/no; exact source URLs | Identifies pages used as sources |
| Third-party evidence | Cited URL and whether it supports a claim about the brand | Separates external corroboration from unrelated links |
| Competitors | Brands named or recommended in the same answer | Supports like-for-like comparison |
| Business outcome | Referral session, declared AI-assisted discovery, or linked CRM opportunity | Keeps visibility and revenue evidence distinct |
Example: keep the denominator and collection date visible
The screenshot below comes from our own Humanswith.ai US/EN project in Hermes and Workspace. The selected 14 October 2026 snapshot contains 400 prompts, 1,993 saved answers and 2,000 planned prompt-engine cells. Seven planned cells were not collected in that snapshot. Preserve that gap rather than treating it as seven negative answers.
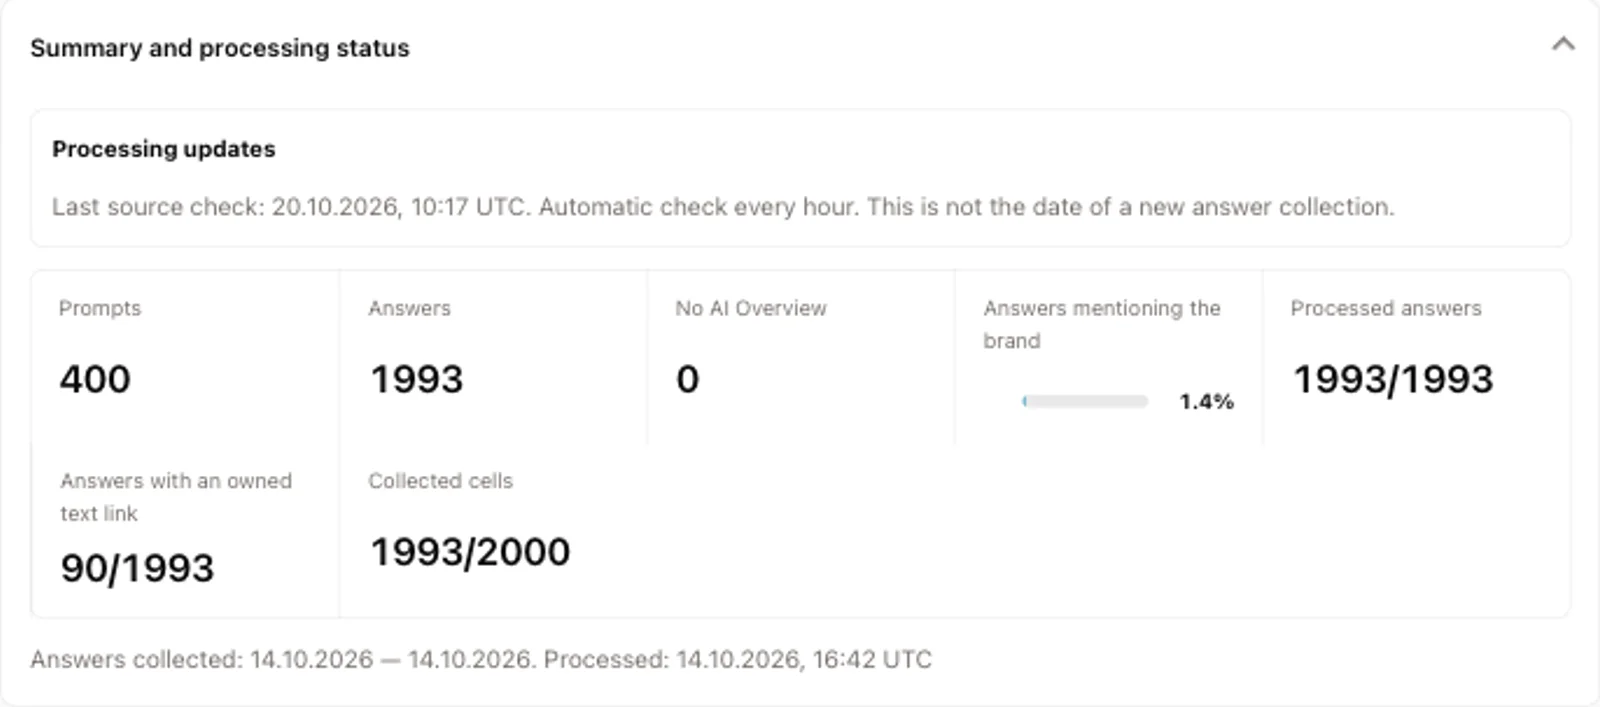
Figure 1. Saved answers collected on 14 October; interface captured on 20 October 2026. “Last source check” is a processing check, not a fresh answer collection.
Open the full-size measurement summary.
Read the labels literally. The screen's 1.4% uses Workspace's literal brand-matching rule across saved answers; it is not a per-engine recommendation rate. “90/1993 answers with an owned text link” is a separate extraction result, not automatically a count of verified supporting citations. Do not combine these fields with a provider's differently defined mention or citation flags.
If Reddit, review sites, analyst pages or other sources recur in the saved answers, investigate their role before choosing an external-presence tactic.
Google's AI-features guidance discusses Search Console alongside analytics for conversions and time on site. Keep search performance and conversion evidence distinct from your prompt-level records of brand mentions and cited sources; the measures answer different questions. [1]
Inspect the exact passage and source link in each saved answer. Do not label a page trusted, recommended, or revenue-producing merely because its URL appears in a source list.
Brand-to-competitor recommendation ratio
The recommendation ratio compares how often engines name your brand against named rivals in the same answer. Absolute share of voice can hide competitive context. A low share looks different when every competitor is also low.
Build the baseline with a fixed process.
- Pick evaluation-stage prompts that name the category, not your brand.
- List the competitors you expect to appear.
- Run the same prompt set across the same engines.
- Score recommended brands separately from passing mentions.
- Calculate your ratio against each rival.
A simple ratio helps executives understand the gap. If a competitor appears far more often, the issue is not “AI visibility” in the abstract. It is a concrete competitive disadvantage.
Repeat the benchmark on a declared cadence and compare only prompt-engine-market combinations successfully observed in both periods. Show the matched sample size, each rate, and the change in percentage points. Report newly added prompts separately. Preserve repeat observations so answer variation remains visible; do not merge carried-forward answers into a fresh collection. If the model, search mode, location, or capture method changes, annotate the break before interpreting a trend.
Two supporting metrics round out the panel. Entity accuracy tracks whether engines describe your company correctly. Wrong pricing, wrong market, wrong category, and wrong geography all count as failures.
Sentiment framing records whether the recommendation is enthusiastic, neutral, or hedged. A brand can be mentioned often and still lose trust if the model frames it with caveats.
Keep business impact beside the visibility benchmark. Referral analytics records visits that reached your site; a citation can exist without a click. Self-reported discovery captures a different signal, such as a prospect naming an AI assistant on a demo form. Link either signal to a CRM opportunity only when the underlying records support the connection, deduplicate the opportunity, and state the attribution window. A rise in citations alone does not prove incremental pipeline or revenue.
Section 04
Step-by-Step AI Visibility Audit Checklist
An AI visibility audit is a read-only benchmark that shows where your brand appears, where competitors win, and which sources shape the answer. A dashboard helps after the baseline exists. The first audit still benefits from manual review.
Automated collection reduces repetitive work. Manual review checks whether the answer is relevant, the citation supports the claim, and the brand was actually recommended rather than merely named.
Record each content or technical change with its publication time. Preserve the earlier answers so a later reviewer can reconstruct the comparison without guessing which version was live.
Step 1 — Build a fixed query set from real customer language
- Pull recent support tickets and sales call notes. Extract the buyer’s exact phrasing.
- Read community threads where buyers discuss the problem. Use Reddit first as language research.
- Sort candidates into buckets: vendor comparison, selection criteria, pricing, and failure modes.
- Weight the list toward narrow, high-intent questions.
- Freeze the list and version it.
The goal is not to invent keyword variants. The goal is to capture how buyers ask before they know your preferred terminology.
A useful query set often reveals a painful gap. Buyers mention competitors, pricing risks, migration fears, and integration details. Many company sites answer none of those questions directly.
Step 2 — Run the queries across three engines
- Query ChatGPT, Perplexity, and Gemini with the same prompts.
- Use fresh sessions with memory and personalization disabled.
- Record brand mention, mention position, sentiment, and competitor set.
- Repeat the process enough to smooth one-off output variation.
- Capture raw answer text for diagnosis.
Run the same set from each market you sell into. Regional answers diverge. A brand can appear in one market and vanish in another.
Expect the first pass to feel uncomfortable. A brand that ranks well in Google can still be absent from AI recommendations. The value of the first audit is the dated baseline.
Step 3 — Map the citation graph
- List every cited domain when an answer includes links.
- Tag each citation as owned, earned editorial, community, directory, or competitor-owned.
- Count how often community platforms appear.
- Note whether cited pages look current and maintained.
- Flag third-party pages that discuss your category but omit your brand.
This is where manual review earns its cost. A dashboard can report which domains appear. A person can read the cited pages and see why they win.
You may find that one old comparison thread shapes many answers. You may find that a directory uses stale pricing. You may find that a competitor’s glossary page defines your category better than your own site.
Example: open the saved answer and inspect its links
This source-list capture is from a real ChatGPT response in run 640, collected on 14 October 2026 at 15:19 UTC. The question asks how a mid-market B2B company should use AEO in Perplexity to compare platforms and agencies. Perplexity is part of the question; ChatGPT is the engine that produced the saved response.
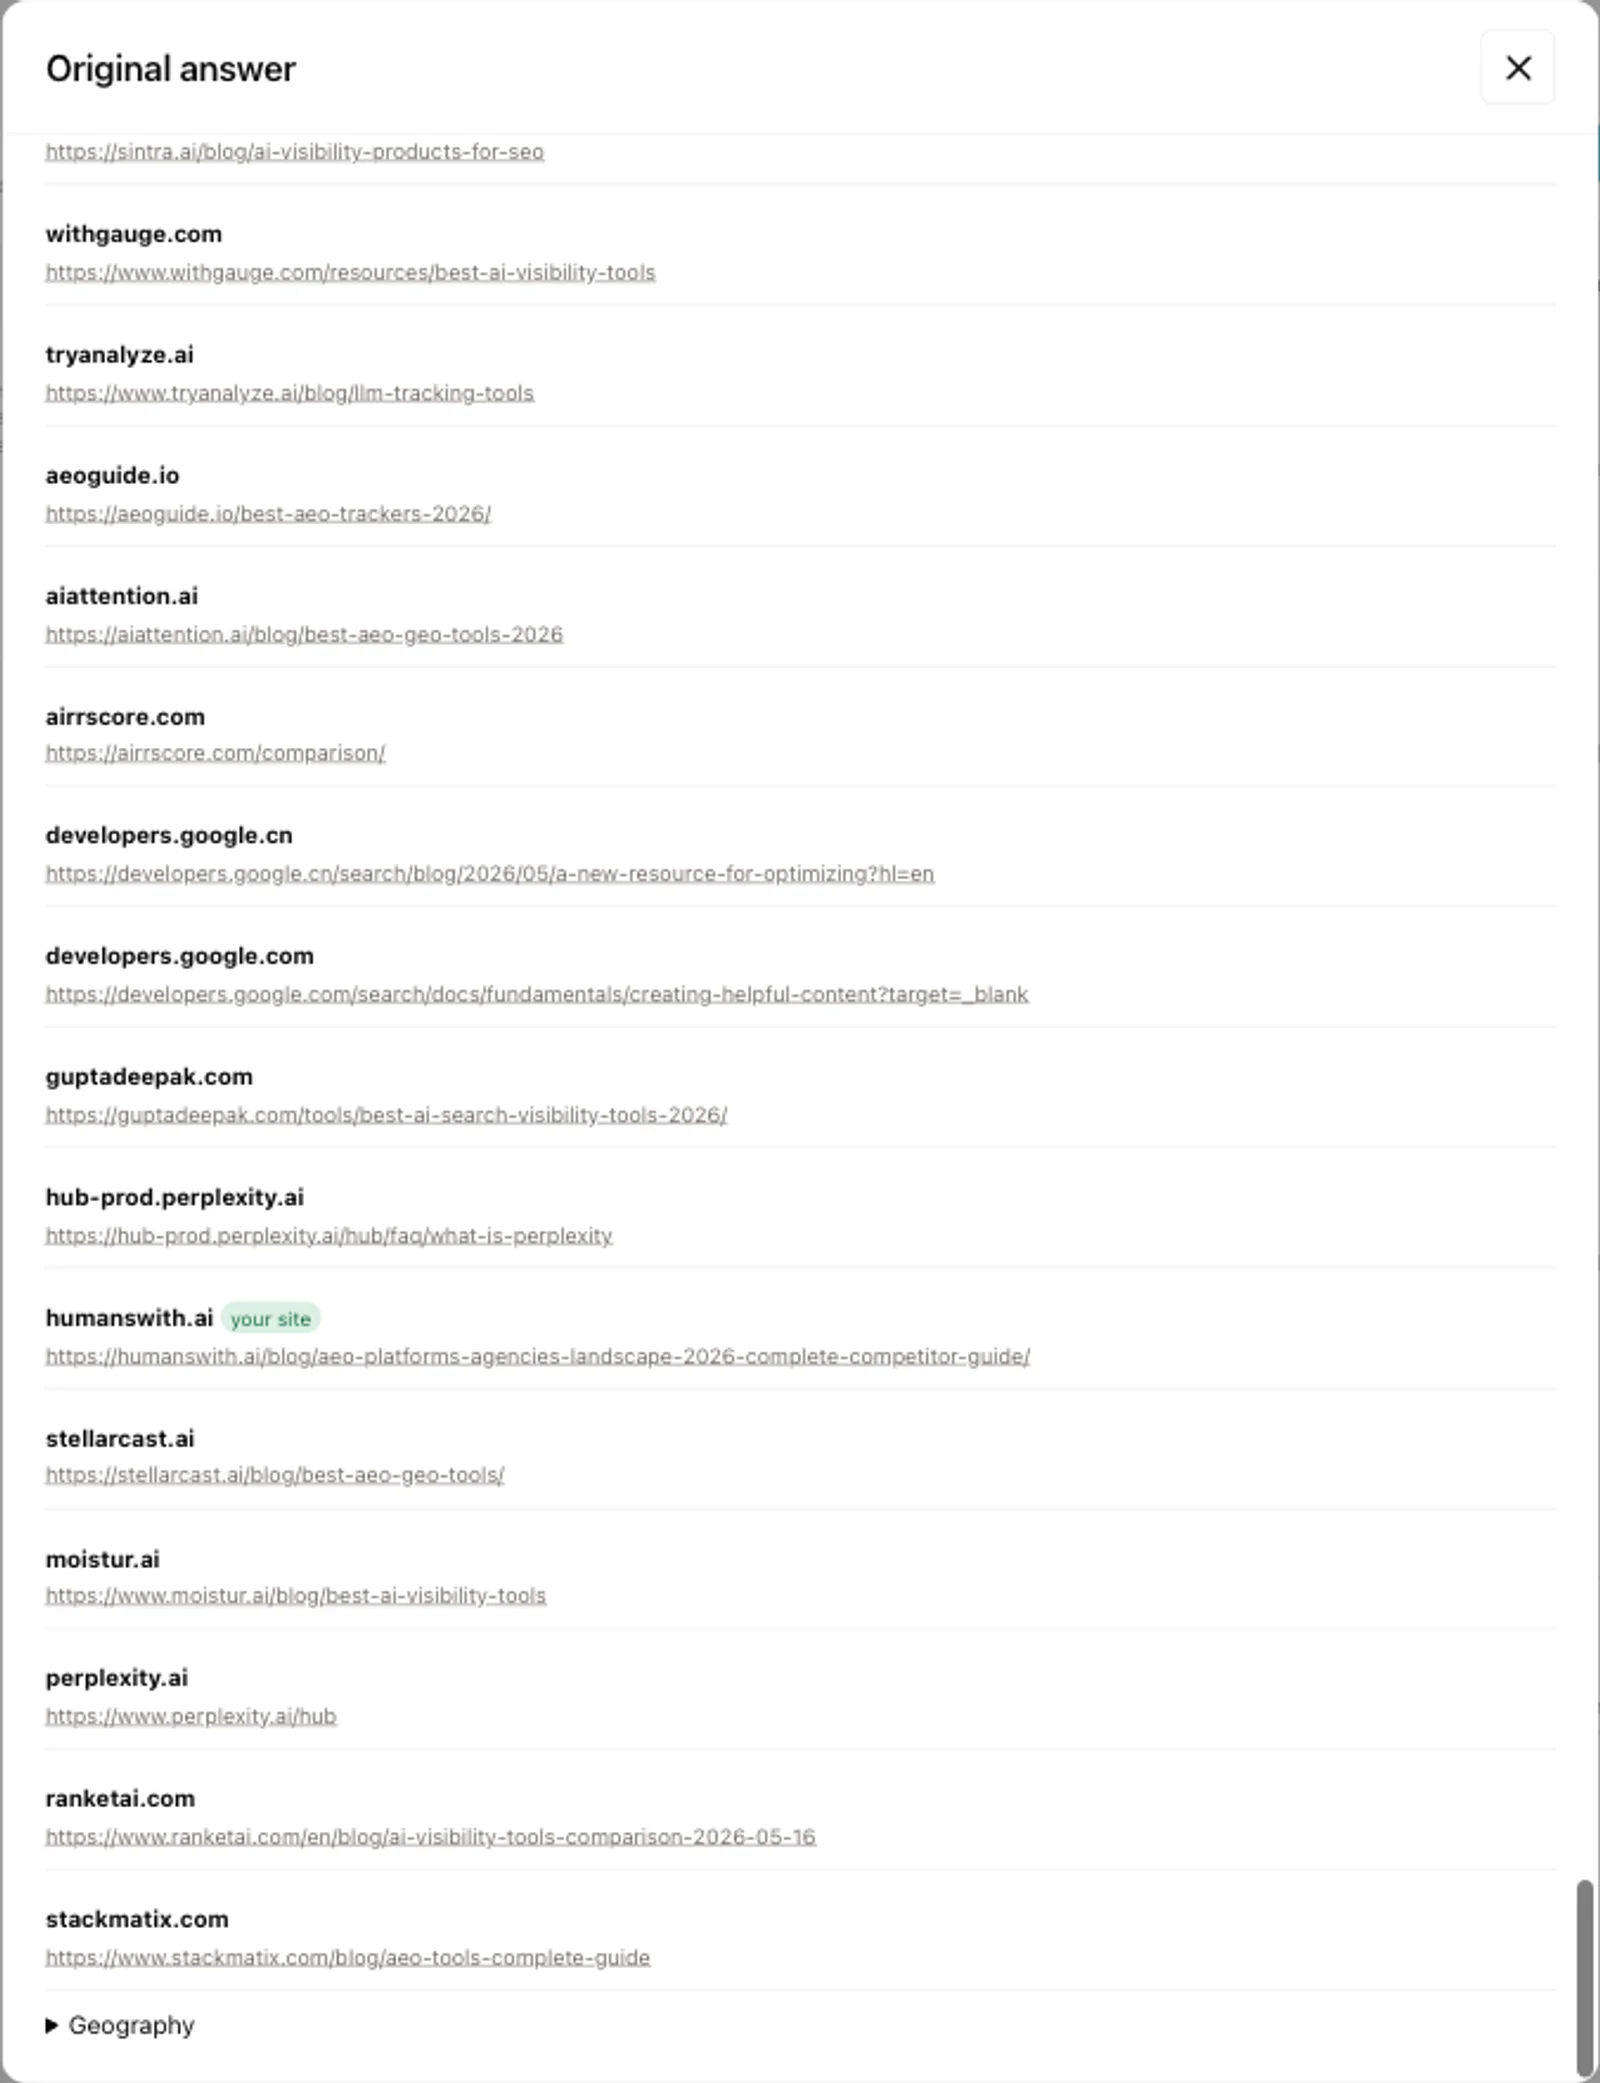
Figure 2. Original-answer source list in our own Workspace, captured 20 October 2026. The full record labels answer-completion metadata as unverified; the visible source list alone does not establish a complete answer or an explicit recommendation.
Open the full-size answer source list.
The “your site” tag identifies a link to our platforms-and-agencies landscape. Inspect the surrounding passage before deciding which claim that link supports. Then use the practical AEO workflow to turn the observation into a page update and a later measurement.
Step 4 — Inspect the pages that already win
- Validate schema on pages engines already cite.
- Check Organization, Product, FAQPage, and Article markup where relevant.
- Confirm visible FAQ copy matches the structured data.
- Score headings, direct answers, comparison tables, and defined terms.
- Compare your cited pages against the competitors that beat you most often.
Differences in structure often matter more than length. A shorter page with clear questions, direct answers, and consistent entity data can beat a longer page that buries the point.
Entity definitions need special attention. The same company name, service definition, founder identity, and proof points should appear across your site, LinkedIn, review platforms, and partner directories.
Audit checklist
- Freeze the prompt set before the first run.
- Separate results by engine and market.
- Record full answer text, not only scores.
- Track brand mentions and citations separately.
- Tag every cited source by type.
- Compare entity descriptions across owned and third-party surfaces.
- Flag inaccurate pricing, positioning, geography, and category claims.
- Review competitor pages that earn repeated recommendations.
- Keep audit workflows read-only.
- Assign an owner to review the proposed page changes and their supporting evidence.
This checklist turns AEO into a repeatable operating rhythm. It also protects the team from chasing anecdotes.
Section 05
Optimizing Content Structure for LLM Extraction
Make the answer easy for a reader to locate and verify. A clear heading, a direct explanation, and supporting evidence reduce ambiguity. Treat possible citation benefits as a hypothesis to measure.
Write headings as the question a buyer actually types
Turn H2s and H3s into questions buyers ask. “Pricing overview” is weak. “How much does an AEO audit cost for a mid-market B2B company?” is stronger.
Use the heading to state the reader's question, and answer it near the start of the section. Follow with conditions, exceptions, and evidence rather than hiding them behind promotional copy.
Three rules keep this practical:
- Match audit phrasing. Use real customer language where it reads naturally.
- Answer immediately. Put the number, range, verdict, or condition before the explanation.
- Keep one question per heading. Compound headings split the answer.
Documentation-style organisation can make detailed information easier to find. Apply it when it suits the reader's task, rather than copying a vendor's visual style as an assumed ranking technique.
Format for readers and assistive technology
Use a table when rows and columns express a real comparison. Use prose for reasoning and limitations, and lists for steps or parallel checks. W3C explains how captions identify tables and how summaries can clarify complex structures. No format is guaranteed to outperform another for every answer engine. [3]
| Information | Useful presentation | Reader check |
|---|---|---|
| Vendor comparison | Table with consistent criteria | Can the reader compare like-for-like options? |
| Pricing | Clear scope, currency, and billing period | Are the inclusions and exclusions explicit? |
| Process | Ordered steps | Is the next action clear? |
| Definition | A short explanation near the heading | Does it answer the intended question? |
| Evidence | Named source, date, and measurement context | Can the claim be verified? |
Bulleted lists work when each bullet stands alone as a complete claim. Fragments do not survive extraction well.
A useful sentence states its conditions: 'The answer links to our pricing page, but the capture does not tell us whether anyone clicked.' This records the observation without turning a citation into a traffic claim.
Keep each section complete enough to make sense on its own. Avoid repeating a summary when the section is already clear.
After publication, check the actual page: links should resolve, tables should remain readable on a phone, and the FAQ should match its markup.
Off-page structure: PR, commentary, and the mentions that build trust
Independent publications and relevant community discussions can corroborate a brand's claims. Inspect the sources cited for your target prompts before choosing an external-presence tactic. A clean page and a third-party mention are not guarantees of selection.
Keep the company's category, offering, and current facts consistent across public profiles. Explain legitimate differences between products or markets instead of forcing every description into the same wording.
Practical moves that compound:
- Named expert commentary. Attribute quotes to a person with a title.
- Proprietary data releases. Publish original evidence that others can reference.
- Consistent proof pages. Keep testimonials and case studies accessible.
- Trade and analyst placements. Earn mentions where buyers already research.
- Founder-led explanations. Give models a clear person-to-brand relationship.
If a brand is cited for definitions but absent from buying recommendations, compare those prompt groups and their cited sources. The pattern is a diagnostic lead, not proof that missing external mentions caused it.
Review page usability and external corroboration separately. Prioritise the work supported by the observed answer gaps.
Section 06
The Role of Reddit and Community Platforms in AEO
Community discussions can contain useful comparisons, objections, and implementation experience. Verify whether those discussions appear among the sources for your own tracked prompts.
Read the original discussion before reusing its wording. A highly visible comment may not represent the broader market or the context of your buyer.
Contribute within the community's rules
Read the platform and community rules before contributing. Disclose relevant affiliation, answer from experience you can substantiate, and do not manufacture independent support. Review moderator feedback before posting again.
That advice matters because Reddit punishes promotional behavior. A high removal rate is not bad luck. It is feedback from moderators and members.
Customer-language research is the underrated half. Read the community before you answer. Note the nouns, objections, comparisons, and failure stories buyers use. Those phrases become headings, FAQ entries, and prompt-test candidates.
Do not treat Reddit as a link-building channel. Treat it as a place to earn trust through useful answers. If the answer does not stand on its own without a link, it is not ready.
Separate useful discussion from verified evidence
A forum comment may contain practical experience, but it can also contain errors, undisclosed promotion, or context that does not apply to your buyer. Verify factual claims before treating them as evidence.
Use implementation discussions to identify questions worth investigating. Support your own answer with records you can verify rather than presenting a community anecdote as a general result.
When a discussion contradicts your public claims, check both against the current product facts. Correct inaccuracies and document legitimate differences in context.
Owned content and community evidence need to agree. That does not mean manipulating discussion. It means fixing the product, the claim, or the page when the market says something different.
Use owned pages for accurate product facts and independent evidence for relevant corroboration. Record which source supports which claim.
A practical workflow for community research
Choose a manageable contribution cadence and assign it to people who can speak from relevant experience. Writing under a founder's name does not make an unsupported claim stronger.
- Pick a small set of subreddits and Quora topics where buyers already discuss your problem.
- Read the rules before posting.
- Spend the first pass reading only.
- Log real question phrasing verbatim.
- Answer only when you can give a specific number, timeline, tradeoff, or failure mode from your own work.
- Disclose affiliation at the start when it matters.
- Answer fully in the comment.
- Avoid gated assets, forced demos, and “DM me” replies.
- Link only when the link is the shortest path to a better answer.
- Never use alternate accounts to manufacture agreement.
- Never ask staff to upvote a thread.
- Log each reply with date, thread, topic, and question phrasing.
- Review removals as a quality signal.
- Feed recurring questions into your content calendar.
- Review later benchmark captures for actual citations of the discussions you monitored; do not assume publication caused any observed change.
On any discussion platform, answer the question directly, preserve necessary context, and disclose relevant affiliation. Follow the platform's rules for promotion and linking.
Identify the author's real role when relevant and permitted. Do not impersonate a customer, fabricate a testimonial, or present commercial advice as independent.
Governance still applies. Reading and logging can be routine. Replies should stay human. Automation can collect evidence, but it should not impersonate experience.
Use tracking tools to find observations worth reviewing. Inspect the saved answer and source before attributing a change to community participation.
Section 07
FAQ
What is the difference between AEO and GEO?
The terms overlap in industry usage. Define your work through measurable outcomes such as brand mentions, recommendations, and source citations rather than assuming that the labels identify separate ranking systems.
What should an AEO benchmark measure first?
Record brand mentions, explicit recommendations, cited URLs, competitor appearances, and factual accuracy. Save the answer and collection conditions so each label can be reviewed. Include the observed sample size and missing captures beside the rates.
How often should a team rerun an AEO audit?
Use a stable recurring cadence. Rerun often enough to catch model drift, but not so often that the team reacts to random variation.
Why does Reddit matter for AEO?
Relevant discussions can reveal buyer questions and may appear in an answer's cited sources. Check your own captures before prioritising Reddit, and follow the platform and community rules when contributing.
Can AEO work replace SEO?
No. Google's AI search guidance still depends on accessible, useful, indexable content. Measure answer visibility alongside search performance and business outcomes rather than substituting one for another. [1]
Does crawler access prove that a page was cited?
No. A crawler request shows access, while a citation requires an observed answer linking to the page. Keep crawler logs, source citations, and human referral sessions as separate records. [2]
Section 08
Sources
[1] AI features and your website — Google Search Central — https://developers.google.com/search/docs/appearance/ai-features
[2] Overview of OpenAI Crawlers — OpenAI — https://developers.openai.com/api/docs/bots
[3] Caption & Summary — W3C Web Accessibility Initiative — https://www.w3.org/WAI/tutorials/tables/caption-summary/
For your team
Stop hiring agencies and freelancers
Hire not agencies and freelancers — but Marketing AI Agents for the AI Search.
- Per-engine citation map across 7 AI engines
- Content + schema work that earns the citation
- Honest 30-min strategy call before you commit
Cited across
- ChatGPT
- Gemini
- Google AIO
- Google AI Mode
- Perplexity
- Copilot
 Otterly.AI,
 Peec AI,
 Scrunch AI,
 Profound, traditional agencies, and