 Humanswith.AI · since 2019



To improve a B2B brand's visibility in AI answers, first measure the buyer questions where it is absent, then update the existing pages that should answer those questions. Check whether each engine mentions the brand, recommends it, and cites a supporting URL. Track visits and qualified opportunities separately so visibility is not mistaken for revenue.
This playbook covers four phases: diagnose brand visibility, maintain canonical pages, make their answers and evidence easy to extract, and research the language buyers use in communities. Each phase should leave a reviewable deliverable. Use the workflow as a test plan; it does not guarantee a citation or a fixed time to results.
In this article
Section 01
What each phase should deliver
| Phase | Deliverable | Completion check |
|---|---|---|
| Diagnose | Versioned buyer prompts and an answer log by engine and market | Mentions, recommendations, citations, and missing observations are recorded separately |
| Maintain canonical pages | A prompt-to-page map with an owner for each update | Existing pages are checked before a new URL is proposed |
| Improve extraction | Revised answers with verifiable evidence and matching visible markup | The published page renders the intended text, links, and structured data |
| Research communities | Buyer questions linked to their original discussions | Affiliation and platform rules are reviewed before any public contribution |
Section 02
Understanding the shift from SEO to AEO and GEO
AEO and GEO are overlapping industry terms for improving visibility in AI-generated answers. This playbook uses AEO for the practical workflow of measuring answers and improving their supporting content. It measures mentions, recommendations, and source citations separately rather than treating AEO and GEO as different ranking systems. Google's guidance for AI features starts with crawlability, indexability, useful content, internal links, and a good page experience. [1]
Start with evidence about your own buyers. Sales conversations, support questions, and saved AI responses can show where an answer engine participates in research. They do not establish that every buyer uses it.
A referral visit can reveal one entry point into the buying journey. A prospect's account of how they found you can reveal another. Keep these observations separate from estimates about how much discovery happens inside AI assistants.
Check how each engine describes your offering before deciding which content to change. An answer can omit the brand, describe outdated pricing, or cite a source that no longer represents the product.
Why measure answers as well as search results?
A page's search position does not tell you whether it was cited or whether the brand was recommended. Save the actual answer and cited URLs, then compare them with search and referral data. A citation is a visibility observation; a conversion requires a separately defined user action.
None of this retires content marketing. A thin page structured perfectly still has nothing worth quoting.
Section 03
Phase 1: Diagnose your brand in the AI-search landscape
Build two prompt groups before collecting answers. Use unbranded buyer questions such as "Which [category] vendors fit [use case]?", "How should we compare [category] providers?", and "What does [category] implementation cost?" to measure discovery. Use questions about your brand's product, pricing, and named alternatives to check accuracy separately. Run a fixed, versioned set on the engines your buyers use. Save one row per prompt, engine, market, and collection time, with the full answer, source URLs, mention and recommendation flags, and observation status. A failed request is not measured. If a completed Google search shows no AI Overview, record that outcome explicitly.
Classify observed gaps before choosing a fix: factual errors, such as outdated pricing; category drift, where the answer describes a different offering; and absence from an otherwise relevant answer. Keep incomplete captures outside this classification. A missing brand in one response is an observation to investigate, not proof that a page is missing or that a particular ranking factor caused the omission.
For factual errors, verify the fact against the current product or pricing record and correct the relevant canonical page. For category drift, reconcile how your homepage, product pages, and public profiles describe the offering. For absence, inspect the actual cited sources and map the buyer question to an existing page before deciding between an update, technical work, or external corroboration. Prioritise repeated gaps on commercially relevant prompts; do not create a new article simply because one answer omitted the brand.
Example: inspect one buyer question in Hermes
Here is a real example from our own Humanswith.ai project in Hermes. We filtered the saved 14 October 2026 snapshot to “How to track ChatGPT citations for enterprise companies.” The five displayed engine responses are marked answered, with no literal brand mention. That identifies a question to investigate; it does not prove that a page is missing or that the brand is absent from every answer.
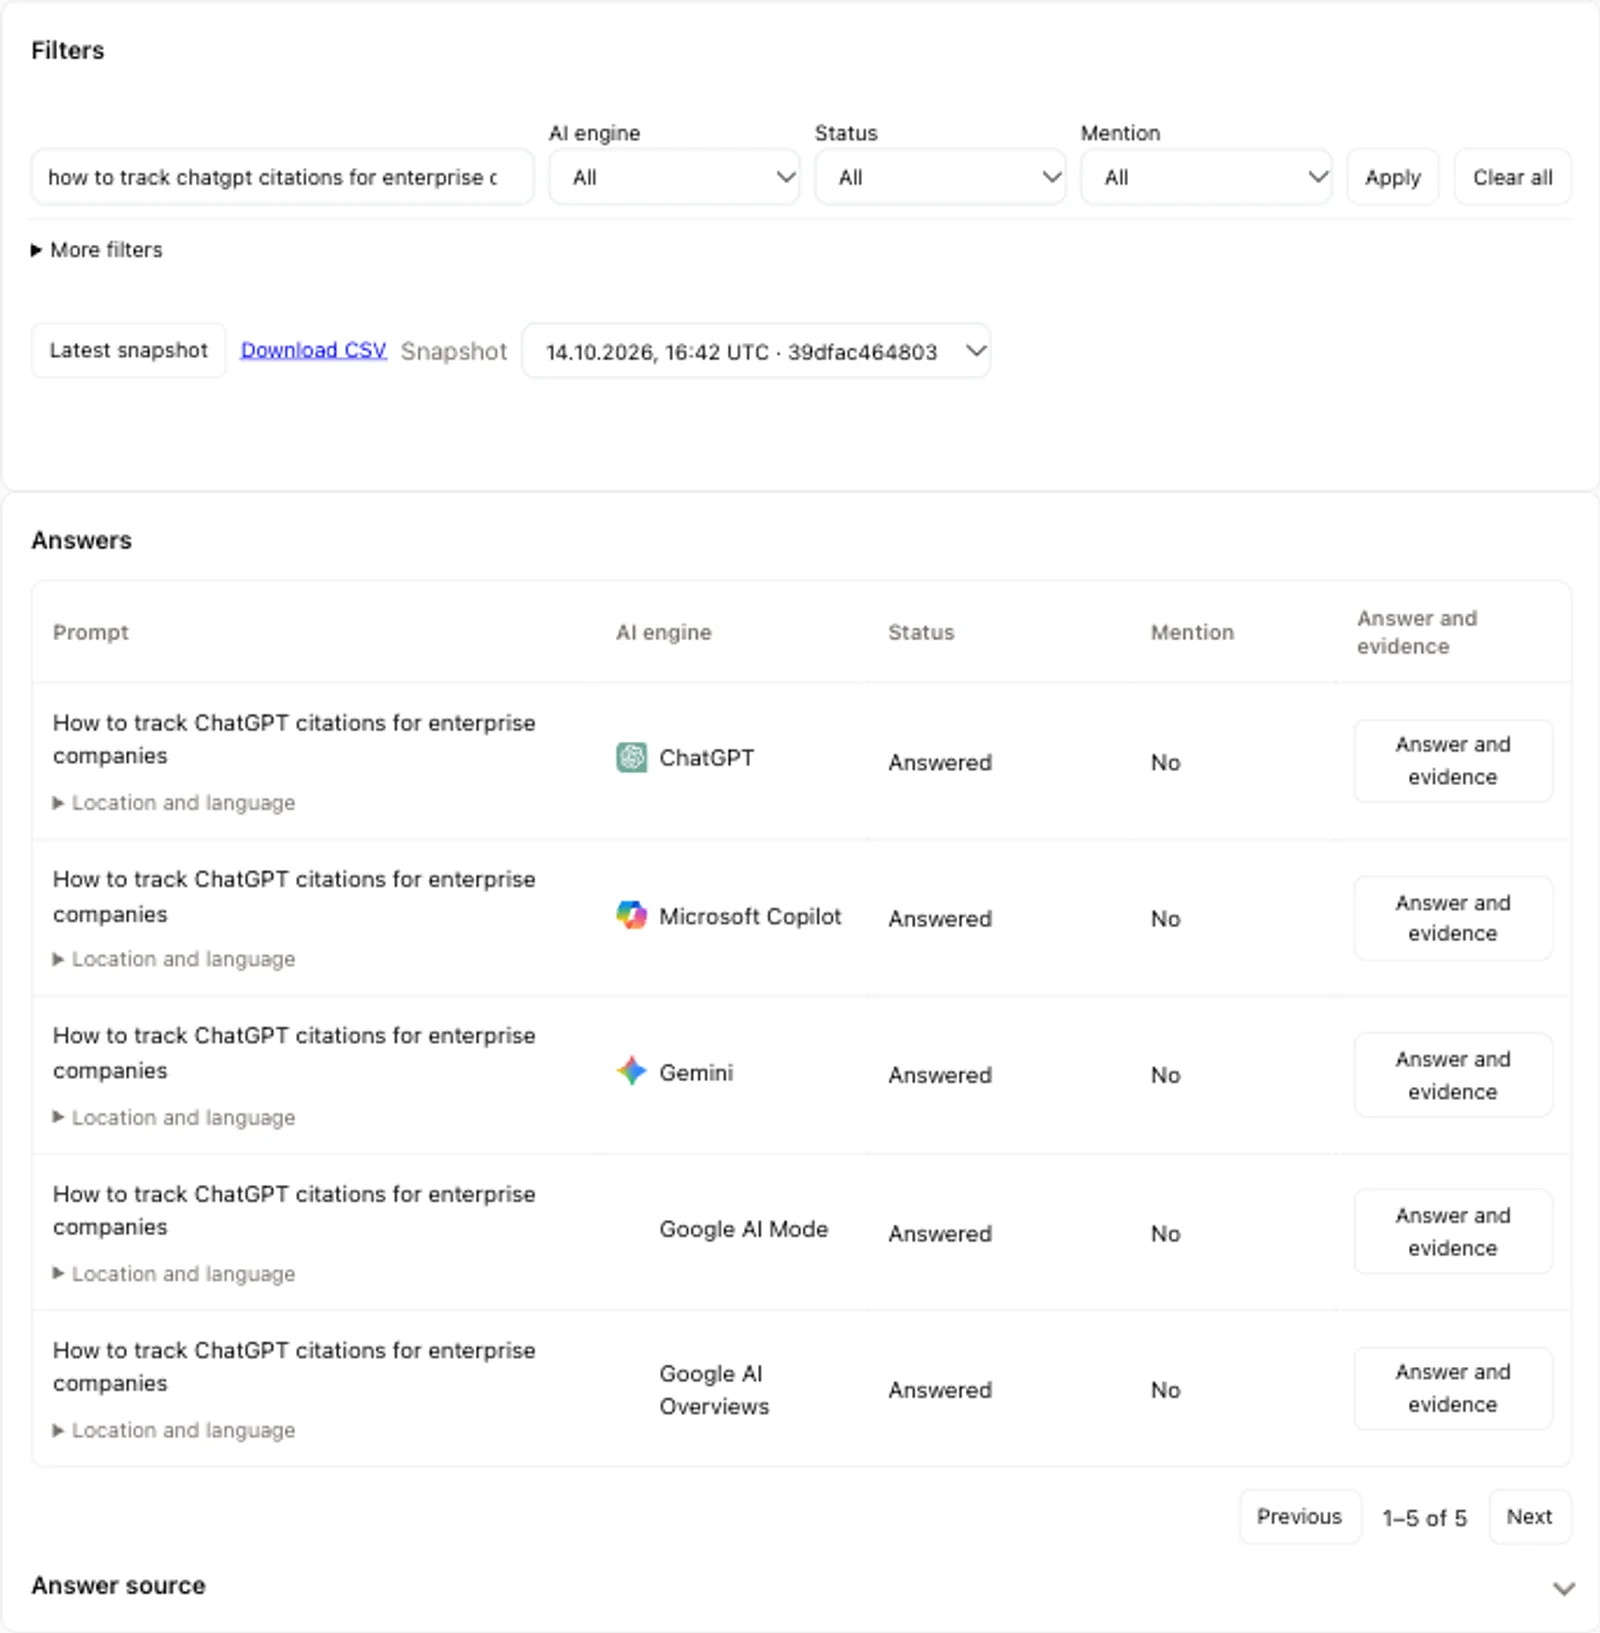
Figure 1. Humanswith.ai's own Workspace, captured 20 October 2026; the selected answer snapshot was processed on 14 October. “ChatGPT” in the question is its topic; the engine column identifies who answered.
Open the full-size prompt comparison.
The next step is to inspect the responses and source URLs, then map the question to an existing page. For denominators, missing observations and repeat comparisons, use the AI-answer benchmarking guide.
Repeat the audit from more than one country
If you sell across the Gulf and the US, collect separate observations for each market and record the actual collection location and language. The vendor list may differ, but the same wording does not guarantee a geographic difference. A run collected elsewhere is a cross-market comparison, not a verified local measurement. Keep the engine and search mode stable when comparing markets.
Make important pages easy to reach
Link product, pricing, documentation, and evidence pages from relevant navigation and related content using crawlable HTML links. A footer can help, but it is not a complete sitemap and its position does not guarantee a citation. Check the rendered links and destination pages rather than assuming a particular CMS or navigation style blocks crawlers. [1]
Keep navigation selective and descriptive. Include pages that help a buyer complete a real task. Avoid repeating large sets of near-identical location or keyword links.
Connect visibility to business evidence
Report citation rates alongside visits and qualified opportunities, with a clear denominator for each. A prospect naming an AI assistant on a demo form is self-reported influence, not proof of incremental revenue. Preserve that distinction when linking the observation to a CRM record, and avoid counting the same opportunity more than once.
Use server logs and referral analytics as supporting evidence. OpenAI distinguishes OAI-SearchBot, which supports search discovery, from GPTBot, which concerns potential model training. Check both robots rules and infrastructure access against the current crawler documentation. A bot request is not a human visit, and the difference between fetched pages and referral sessions does not identify why a page was not cited. [2]
Phase 1 checklist
- Audit a versioned prompt set across the engines your buyers use, separating unbranded discovery from branded accuracy checks
- Log every answer verbatim and tag each error as factual, category drift, or absence
- Re-run the audit from each market you sell into
- Check that product, pricing, documentation, and case-study pages have relevant crawlable internal links
- Set up tracking for AI-influenced revenue on the demo form and in first-call notes
- Pull crawler hits from server logs and AI referral sessions from GA4 as your baseline
Section 04
Phase 2: Build canonical, fresh content for LLM crawlers
Choose the canonical pages that answer your buyers' most important questions: product, pricing, implementation, comparisons, and substantiated case studies. Map each question to an existing URL and assign an owner. The appropriate number depends on your offering and maintenance capacity; there is no universal page-count target.
Review canonical pages when their facts change and on a maintenance schedule the team can sustain. A visible update date helps readers judge currency, but it should describe a real publication or substantive revision. Google's byline guidance recommends clear visible dates and consistent structured dates; it does not establish a fixed percentage increase in AI citations. [3]
Show an accurate update date
Use a visible publication or update date where it helps readers. Keep it consistent with the page's structured data. Treat freshness as an editorial maintenance responsibility, not a promised citation lift.
Change the update date when the article changes substantially. Retain older research when it remains relevant and identify its date and scope. Replacing the year in a heading does not make the underlying evidence current.
What a quarterly refresh actually involves
A refresh is not a rewrite. Work through four things per canonical page:
- Statistics. Check the original source, sample, collection date, and scope. Keep older findings when they are still relevant, clearly labelled as historical where necessary.
- Case studies. Use named, permitted examples with a traceable baseline, observation window, and outcome. A newer case is not automatically better evidence for a different use case.
- Product changes. Every feature shipped since the last pass, and every feature retired.
- Pricing. Match the page to the current rate card exactly, including currency and billing period.
Add a comparison, FAQ answer, or illustration only when it answers a demonstrated reader question. Keep a brief change log so later measurements can be associated with a documented intervention.
Before revising a pricing or implementation claim, ask its owner to confirm the current facts. Record who approved the change and which public page or project record supports it. This avoids replacing an old unsupported statement with a new one.
Schema for the date
Express dates in structured data as well as visible text. Use an appropriate ISO 8601 value for datePublished and, when applicable, dateModified. A human-readable date and a machine-readable timestamp can have different formats while referring to the same event. Keep their meanings and time zones consistent. [3]
Phase 2 checklist
- Select canonical pages from the prompt-to-page map and assign a named owner to each
- Add a visible "last updated" date to each canonical page template
- Keep structured publication and modification dates consistent with the visible dates
- Schedule quarterly refreshes with statistics, case studies, product changes, and pricing as fixed line items
- Log citation rate per canonical page before the first refresh, then compare after one quarter
Section 05
Phase 3: Structure content for direct AI extraction
Open a section with a useful answer to its heading, then provide the conditions and supporting evidence. A reader should understand the point without searching several paragraphs. Do not force a brand name into every sentence or treat an answer-first layout as a guaranteed ranking factor.
A page can be retrieved without appearing among an answer's cited sources. That observation does not establish why it was omitted. To investigate, compare the saved answer, the actual citations, page accessibility, and the relevance and evidence of the competing passages. Do not turn a study-specific retrieval percentage into a universal explanation of model behaviour.
Five checks for a useful, accessible page
Use these editorial and technical checks before retesting. They support readers and crawlability; none guarantees selection by an answer engine. Google recommends useful page experience, while W3C explains how captions and summaries help readers identify and navigate tables. [1][4]
| Check | What to verify |
|---|---|
| Direct answers | Headings describe real questions and the text answers them clearly |
| Appropriate markup | Structured data describes the visible page and the applicable content type |
| Verifiable evidence | Named claims link to sources with a clear date and scope |
| Readable structure | Tables compare related data; lists describe genuine steps or checks |
| Maintenance | Product facts, links, and update dates remain accurate |
Choose a format that fits the information. A table can clarify a comparison, but prose may explain a limitation better. Neither a minimum word count nor a fixed number of headings establishes citation quality.
JSON-LD without the cargo cult
Use Article or BlogPosting markup for editorial pages and BreadcrumbList where it represents the site's navigation. If FAQPage markup is present, its questions and answers must match the visible FAQ. Google's AI-features guidance does not prescribe special schema for inclusion. Valid markup and a readable FAQ do not guarantee an AI citation or a search-result enhancement. [1]
Keep visible answers and structured answers consistent. Validate the JSON-LD and inspect the rendered page after deployment. A successful CMS save does not prove that the public page or its metadata updated.
Use Organization and other schema types when they accurately describe the page or business. Do not add unrelated types or entity links to chase a promised citation effect. Check applicability against the relevant provider documentation.
Named entities and real numbers
Replace vague performance claims with verifiable evidence when it exists. Name the client only with permission, define the metric, and give its baseline and measurement period. If a result is hypothetical, label it as an example; if no supporting record exists, remove the number rather than inventing a more specific one.
Example: separate publication readiness from outcomes
Our ContentOS workflow and Workspace article library separate the content package from its publication and subsequent measurement. The real card below is for a different Humanswith.ai article, Why llms.txt Won't Save Your AI Visibility in 2026. Its text, cover, alt text, schema, approval and website checks are marked ready, while citation and traffic outcomes remain marked not measured.
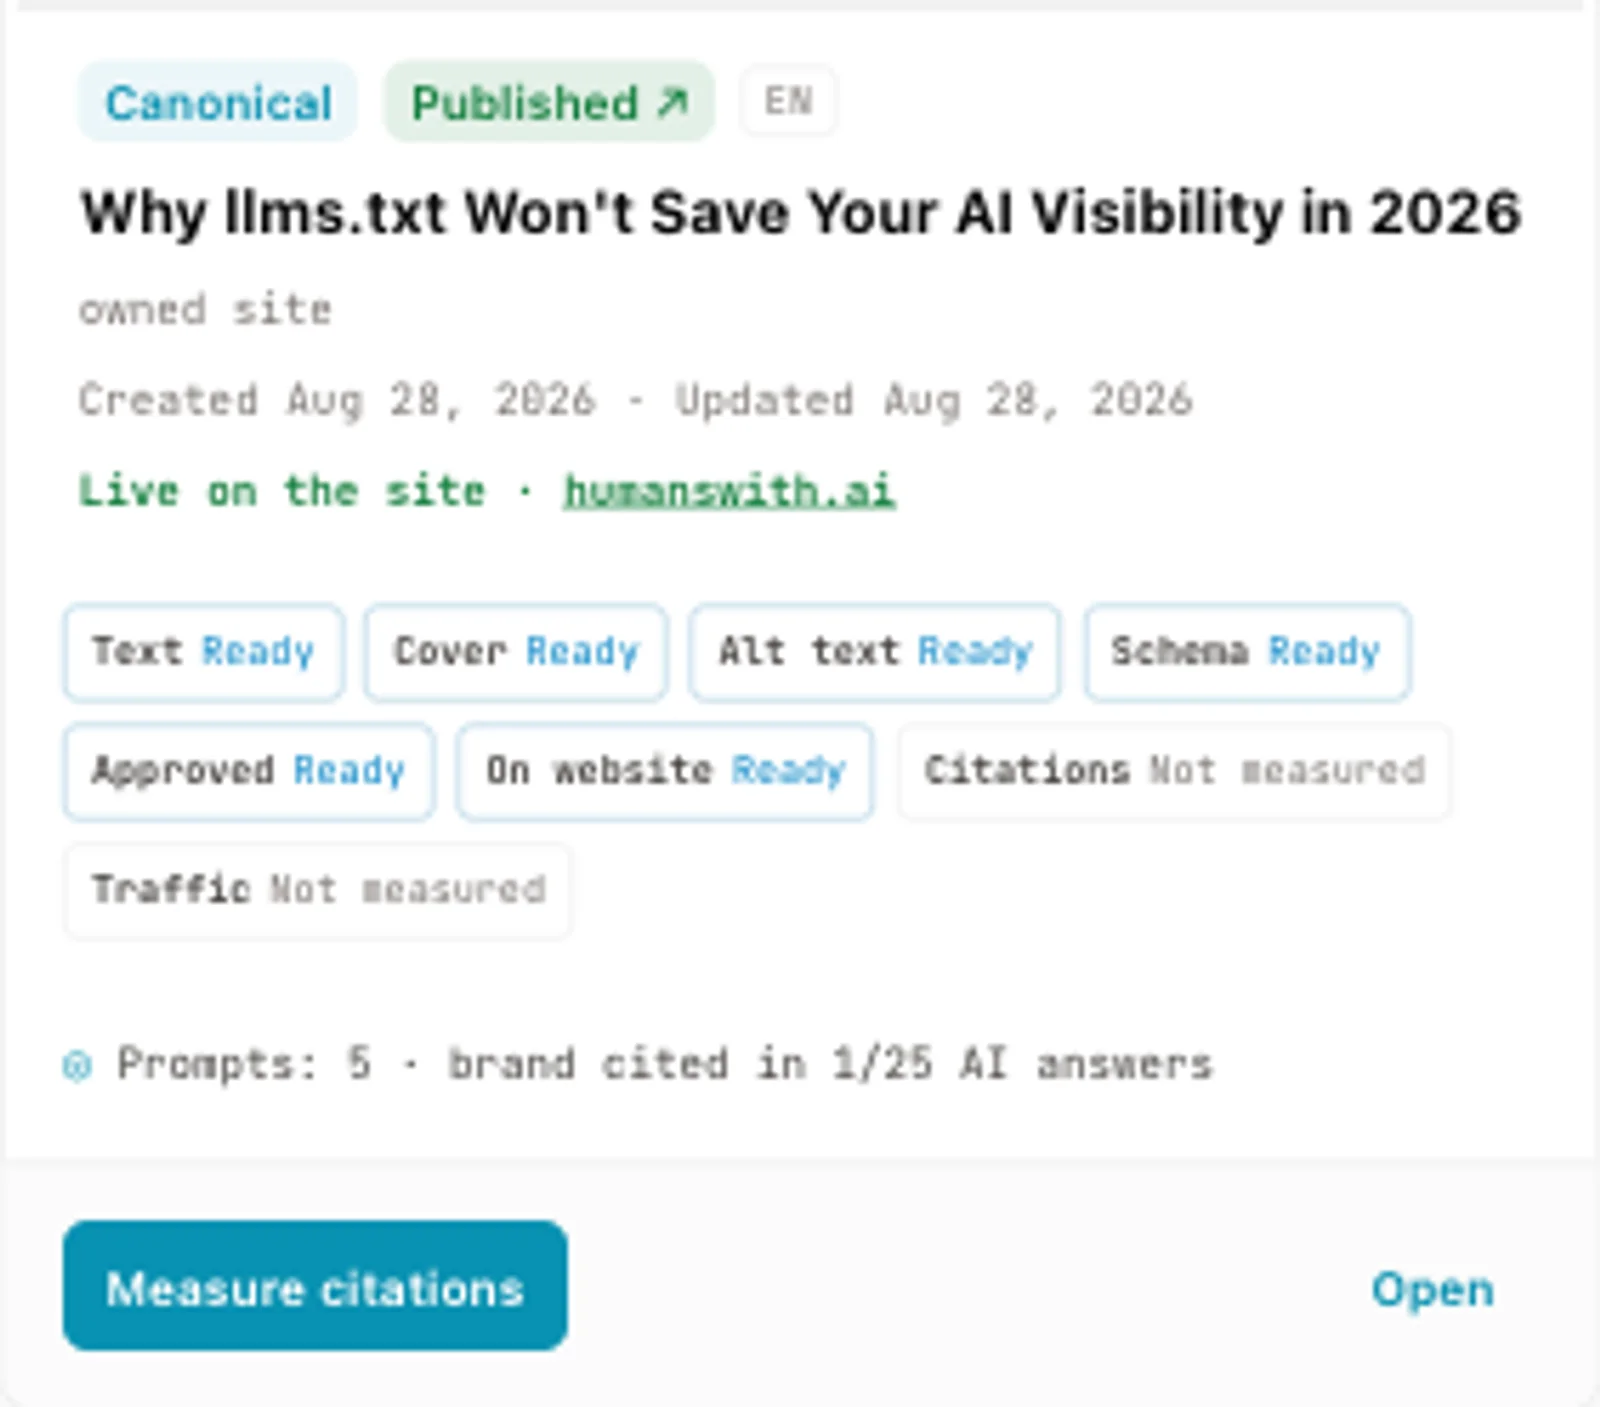
Figure 2. Publication-status detail from our own article library, captured 20 October 2026. The August dates belong to that stored article package. The linked-prompt sample shown on the card is not a before-and-after result for the publication.
Open the full-size publication-status detail.
Use this distinction in your own acceptance checklist: verify the published page, then measure its outcome separately. A green publication check cannot establish that the article increased citations or revenue.
Test, do not assume
Test the engines and search modes in your baseline. Preserve the response, its source panel where available, the collection conditions, and the exact cited URLs. Keep Gemini, Google AI Overviews, and Google AI Mode separate. A clean browser session reduces some personalisation but does not prove that results are identical across users or markets.
Verify the public text and technical changes immediately after deployment. Measure answer visibility later on the declared collection cadence, allowing for discovery and indexing delays. There is no universal two-to-four-week deadline for a citation, and a later change in results does not by itself prove that the edit caused it.
Phase 3 checklist
- Rewrite the first sentence of every section on canonical pages as a standalone answer
- Validate applicable structured data and confirm it describes the visible page
- Verify visible FAQ text and FAQPage schema match word for word
- Replace unsupported claims with sourced evidence or remove the claim
- Use tables or lists only where they make the answer easier to understand
- Retest the baseline engines on the declared cadence and record method changes
Section 06
Phase 4: Leverage community platforms for language research
Use community discussions to learn how buyers describe their problems. Preserve the original wording and discussion context, then compare it with sales and support evidence before using it in a heading or FAQ.
Choose communities where relevant buyers actually participate. Record recurring questions, their source threads, and the context that makes them relevant. Prioritise by repetition and commercial relevance rather than by a fixed number of subreddits, months, or questions.
For example, a buyer may describe an uncontrolled purchasing problem in everyday language instead of using the category term 'spend management'. Treat this as an illustrative wording exercise, not a client case or a measured citation result. Verify the language in real research before changing a page.
Rules of engagement, and why they are not optional
Read the platform rules and each subreddit's rules before posting.
- Reply only when you can genuinely help inside the community's rules.
- Write self-contained, experience-led answers. If the reply only works when someone clicks your link, it is an ad.
- Disclose relevant affiliation openly. "I work on a tool in this space, so weigh that" costs nothing and protects everything.
- Never simulate independent support for your own product.
- Never buy aged accounts and never coordinate votes.
- Track removals and moderator feedback, and read the platform's current rules before contributing. Treat a request to stop or change your approach as a reason to review the work rather than repeat the same post.
A removed post is a reason to review the applicable rule and context. Record the moderator's stated reason where available; do not assume every removal has the same cause.
What good looks like
A useful reply answers the question in the comment itself and distinguishes direct experience from assumptions. Include relevant limitations and disclose affiliation. Link only when permitted and useful to the reader. These practices support credible participation; they do not guarantee that an AI engine will quote the discussion.
Phase 4 checklist
- Map recurring questions from relevant communities, preserving wording and context
- Use validated buyer questions to improve existing FAQ entries and section headings
- Read platform and subreddit rules before any account posts
- Draft self-contained, experience-led replies that need no click to be useful
- Disclose brand affiliation openly in every reply where it is relevant
- Track removed posts and moderator warnings monthly as a quality metric
Section 07
Where this leaves your 2026 plan
AEO work depends on useful content, accessible pages, and evidence that can withstand a reader's checks. Use the measured gaps to decide which existing pages to improve first.
Start with a versioned prompt set and an answer log, separated by engine and market. Map repeated gaps to existing pages, select the phase that addresses the evidence, and record the change before measuring again.
Section 08
FAQ
How do you track ChatGPT citations for an enterprise brand?
Use a versioned prompt set and record whether each successfully observed ChatGPT answer mentions the brand, recommends it, or cites an owned URL. Store the full answer and collection conditions. Inspect OAI-SearchBot access separately from human referral sessions, and connect visits to defined conversion events only where the records support it. Neither crawler activity nor a missing referral proves citation success or failure. [2]
How do you track Perplexity citations?
Save the Perplexity answer and source links when available. Record the exact URL, its relationship to the claim, and the product or search mode. Source-list position can be logged, but it is not a measured click-through rate. Compare the same prompt and market conditions on the next scheduled collection.
How do you track Google AI Overviews citations?
Record whether an AI Overview appeared for each completed observation, then save its linked sources, query, date, language, and location. Keep failed captures separate. Google's AI-features guidance describes Search Console and analytics as complementary ways to assess performance. Retain direct answer captures for prompt-level citation evidence: a fall in aggregate organic clicks alone cannot establish that an Overview summarised a particular page. [1]
Does AEO replace classic content marketing?
No. AEO and GEO restructure and distribute content that already has substance; they cannot manufacture substance. A thin page with perfect JSON-LD still gives a model nothing worth quoting.
What is the difference between AEO and GEO in one sentence each?
AEO and GEO are overlapping labels for improving visibility in AI-generated answers. Define the actual outcomes in your measurement plan: mention, recommendation, citation, visit, and business result.
How long before AEO work shows results?
There is no reliable universal time to first citation. Confirm that the revised page is publicly available, then repeat the same measurement after the relevant discovery and indexing interval. Set review dates as an operating schedule, not a performance guarantee. Report unchanged or missing results as clearly as gains.
Section 09
Sources
[1] AI features and your website — Google Search Central — https://developers.google.com/search/docs/appearance/ai-features
[2] Overview of OpenAI Crawlers — OpenAI — https://developers.openai.com/api/docs/bots
[3] Influencing your byline dates in Google Search — Google Search Central — https://developers.google.com/search/docs/appearance/publication-dates
[4] Caption & Summary — W3C Web Accessibility Initiative — https://www.w3.org/WAI/tutorials/tables/caption-summary/
For your team
Stop hiring agencies and freelancers
Hire not agencies and freelancers — but Marketing AI Agents for the AI Search.
- Per-engine citation map across 7 AI engines
- Content + schema work that earns the citation
- Honest 30-min strategy call before you commit
Cited across
- ChatGPT
- Gemini
- Google AIO
- Google AI Mode
- Perplexity
- Copilot
 Otterly.AI,
 Peec AI,
 Scrunch AI,
 Profound, traditional agencies, and